TwelveLabs releases video analysis model to improve training for robotics and autonomous systems
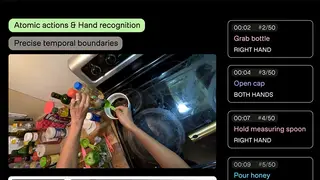
TwelveLabs unveiled Pegasus 1.6, an AI model designed to analyze first-person video footage and extract structured knowledge for physical AI applications. The model enables robotics developers and teams building autonomous systems to convert real-world video data into actionable training information without manually processing raw footage. The technology addresses a critical bottleneck in physical AI development by translating human actions and behaviors captured on video into machine-readable insights.
TwelveLabs, established in 2021, has developed a comprehensive video intelligence platform combining its Marengo and Pegasus models to process footage at human-level comprehension speeds. The company positions Pegasus 1.6 as addressing a fundamental obstacle in robotics development: converting unstructured real-world video into machine-readable training data. By focusing on first-person perspectives rather than traditional broadcast or cinematic footage, the model captures nuanced details—such as grip adjustments and recovery techniques—that robots require to perform complex physical tasks.
The five supported workflows include action segmentation and labeling, enabling automated time-stamped annotations of tasks and hand-object interactions. Notably, Pegasus 1.6 operates with standard cameras rather than proprietary hardware, and accepts both video and still images as input sources. This flexibility potentially broadens accessibility for robotics teams and autonomous systems developers seeking to leverage human demonstration data for model training.
Pegasus 1.6 could accelerate robotics development by reducing manual annotation labor and enabling broader training datasets derived from everyday video footage. Manufacturers and warehouse operators might achieve faster deployment of autonomous systems, while companies operating remote robotics could improve training efficiency. However, widespread application depends on how reliably the model extracts actionable insights across diverse environments and task types, and whether organizations can ethically source and deploy video training data from human workers.