New Method Runs Asynchronous GRPO Training Without NCCL
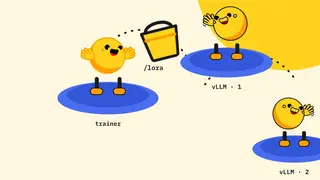
The post describes a technique for executing asynchronous GRPO with LoRA across multiple Hugging Face jobs, using a bucket and proxy to replace NCCL communication. This approach could simplify distributed reinforcement learning infrastructure and reduce dependency on specialized networking libraries.
The technique outlined in the post centers on running asynchronous GRPO — a reinforcement learning algorithm — alongside LoRA, a parameter-efficient fine-tuning method, across multiple Hugging Face jobs. Rather than relying on NCCL, a standard communication library for GPU clusters, the approach substitutes a bucket and proxy mechanism to coordinate between jobs.
This substitution matters because NCCL typically requires tightly coupled, high-performance networking. By removing that requirement, the method could make distributed reinforcement learning more accessible to teams working with simpler infrastructure, potentially lowering the barrier for experimenting with large-scale training setups.
The approach could lower infrastructure barriers for researchers and smaller organizations experimenting with distributed reinforcement learning. By reducing reliance on specialized networking libraries, teams with modest hardware setups may find it easier to scale training across multiple jobs. This could accelerate experimentation in open-source AI development, potentially broadening who contributes to advancing reinforcement learning techniques. However, the practical trade-offs in performance, reliability, and ease of adoption remain to be seen, and the technique's real-world impact will depend on how widely it is adopted and validated by the community.