Three Design Principles Drive Efficiency in Large-Scale AI Computing Infrastructure
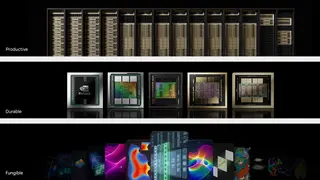
NVIDIA outlined how AI factory operators evaluate infrastructure investments by measuring earning capacity, useful life, and demand flexibility across megawatt-scale deployments costing roughly $60 million per megawatt. The company's GPU platforms are engineered for productivity through high token throughput per megawatt, durability to maintain performance across multiple years, and versatility to handle diverse AI and non-AI workloads. This multi-dimensional approach maximizes return on investment in large data center operations.
Large-scale AI computing facilities operate under a capital-intensive model where each unit of power capacity represents a $60 million investment. Operators evaluate these commitments through three interconnected variables: revenue generation from token production, hardware longevity before performance degradation, and the range of applications the infrastructure can support. The interplay between these factors means that superior performance in one dimension cannot compensate for deficiencies elsewhere—a facility with high output capacity but limited market demand, or cutting-edge equipment with a short viable lifespan, will underperform economically.
NVIDIA's approach addresses all three dimensions simultaneously through integrated system design and software optimization. By maximizing tokens produced per unit of power consumed, extending the productive lifetime of installed hardware through software updates, and enabling diverse workload types beyond AI applications, the company's platforms aim to improve returns across the full operational lifecycle rather than optimizing any single metric in isolation.
This efficiency framework could influence how billions in infrastructure capital flows to data center expansion. Computing providers and enterprises making deployment decisions may increasingly prioritize total-cost-of-ownership over peak performance specifications, potentially favoring vendor ecosystems demonstrating longevity and workload flexibility. Broader impacts may extend to energy consumption patterns—if efficiency gains expand economical use cases faster than power consumption per task decreases, aggregate grid demand could accelerate despite per-token improvements.